An AI-powered job discovery system that reads a resume, searches multiple job boards, filters and deduplicates real job listings, and ranks opportunities by relevance.
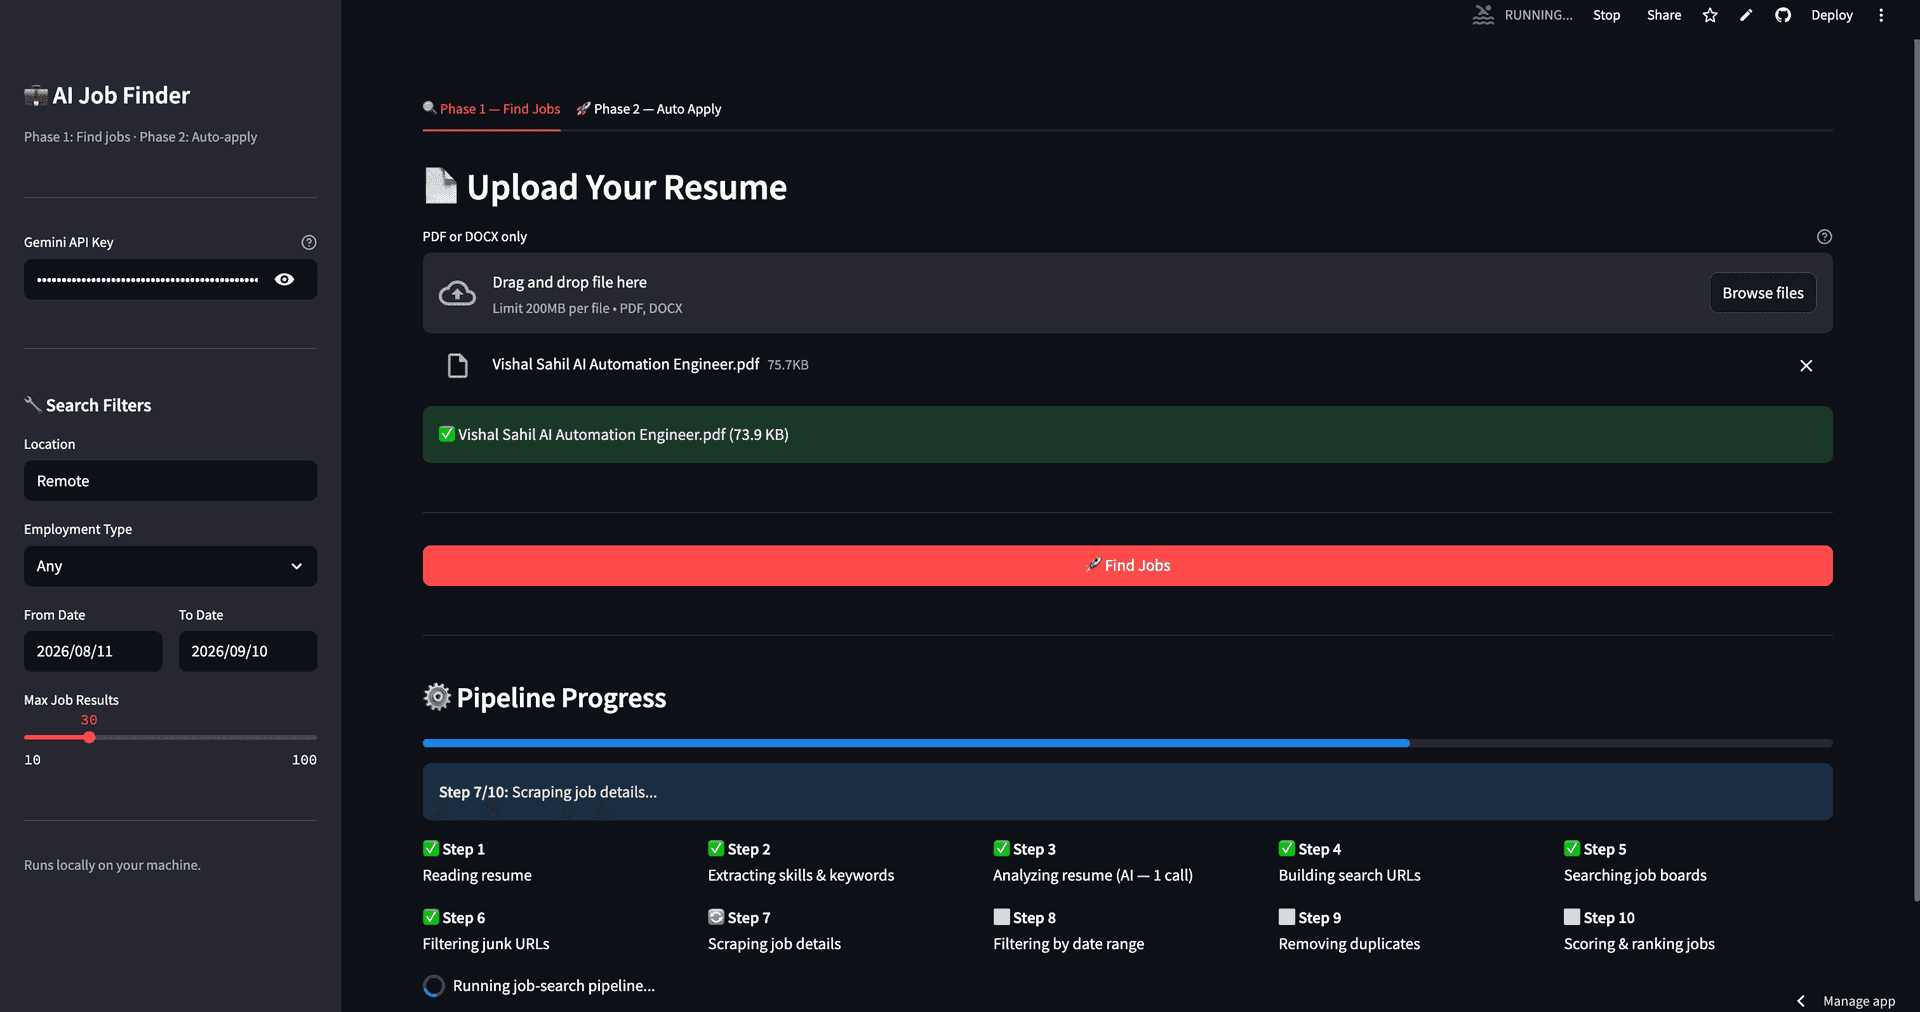
I built a ten-stage Python pipeline that automates the discovery and ranking process. Resume information is extracted using pypdf or python-docx, candidate skills are identified using Python rules, Gemini analyzes the profile once per run, and optimized searches are generated across multiple job sources. BeautifulSoup and Playwright collect job information, while Python handles date normalization, filtering, duplicate removal and relevance scoring before Streamlit presents the final ranked results.
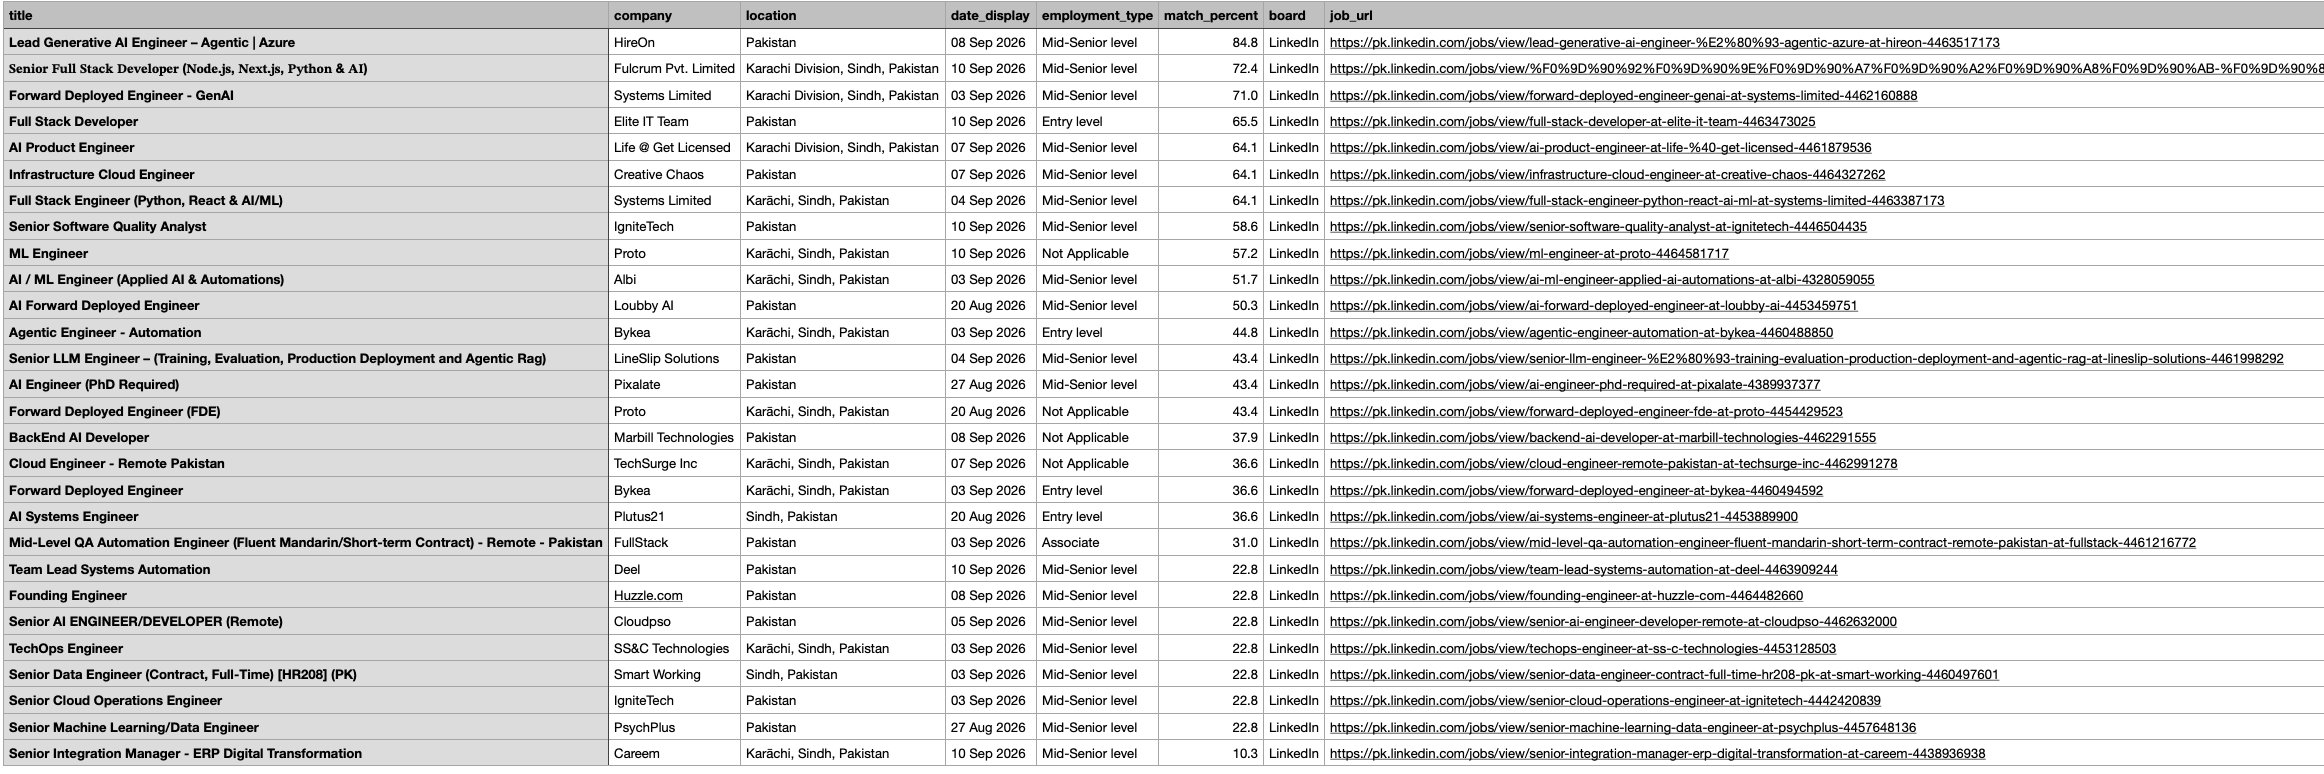
Multi-Agent Job Finder DemoResume Analysis & Job SearchRanked Job Matches
THE SYSTEM, STEP BY STEP
System flow
01Resume Upload
→
02Resume Reader
→
03Keyword Extractor
→
04Gemini Analyzer
→
05Query Optimizer
→
06Job Search Agent
→
07URL Filter
→
08Job Scraper Agent
→
09Date Normalizer
→
10Duplicate Remover
→
11Relevance Scorer
→
12Ranked Streamlit Results
Click Play a Run to follow the system from start to finish.
What it is
Multi-Agent Job Finder is a Streamlit-based job discovery application that turns an uploaded PDF or DOCX resume into ranked job opportunities. The system extracts candidate information, uses a single Gemini call to analyze the resume and create search queries, searches multiple job platforms, scrapes job details, normalizes posting dates, removes duplicate results and calculates a relevance score before displaying ranked job cards.
The problem it solves
Searching for relevant jobs manually requires repeatedly visiting different job boards, rewriting search queries, checking posting dates and comparing each role against a resume. Results can also contain duplicate listings, irrelevant pages and jobs that do not closely match the candidate's experience.
How it works
PDF and DOCX resume upload
Resume text extraction with pypdf and python-docx
Python-based skill, title, location and experience extraction
100+ skill keyword dictionary
Single Gemini API call per job-search run
AI-generated candidate profile and search queries
Multi-job-board search pipeline
LinkedIn job discovery
Rozee.pk job discovery
Indeed job discovery
Glassdoor job discovery
Mustakbil job discovery
Google Jobs discovery
Automatic generation of up to 18 job-board search URLs
BeautifulSoup static job scraping
Playwright support for dynamic job pages
Automatic junk URL filtering
Multi-format job posting date parsing
From-date and to-date filtering
URL normalization for duplicate removal
RapidFuzz title and company duplicate detection
Five-signal relevance scoring system
Percentage-based job match ranking
Ranked Streamlit job cards
Job source and posting date display
Direct job application links
CSV results download
Resume processed in memory without database storage
The engineering focus
I built a ten-stage Python pipeline that automates the discovery and ranking process. Resume information is extracted using pypdf or python-docx, candidate skills are identified using Python rules, Gemini analyzes the profile once per run, and optimized searches are generated across multiple job sources. BeautifulSoup and Playwright collect job information, while Python handles date normalization, filtering, duplicate removal and relevance scoring before Streamlit presents the final ranked results.
Built with
PythonStreamlitGoogle Geminipypdfpython-docxBeautifulSoupRequestsPlaywrightdateparserpython-dateutilRapidFuzzPydantic SettingsLangChain Google GenAI